def BaseLoss( loss_cls, # Uninitialized PyTorch-compatible loss*args, axis:int=-1, # Class axis flatten:bool=True, # Flatten `inp` and `targ` before calculating loss floatify:bool=False, # Convert `targ` to `float` is_2d:bool=True, # Whether `flatten` keeps one or two channels when applied**kwargs):
Same as loss_cls, but flattens input and target.
Wrapping a general loss function inside of BaseLoss provides extra functionalities to your loss functions:
flattens the tensors before trying to take the losses since it’s more convenient (with a potential tranpose to put axis at the end)
a potential activation method that tells the library if there is an activation fused in the loss (useful for inference and methods such as Learner.get_preds or Learner.predict)
a potential decodes method that is used on predictions in inference (for instance, an argmax in classification)
The args and kwargs will be passed to loss_cls during the initialization to instantiate a loss function. axis is put at the end for losses like softmax that are often performed on the last axis. If floatify=True, the targs will be converted to floats (useful for losses that only accept float targets like BCEWithLogitsLoss), and is_2d determines if we flatten while keeping the first dimension (batch size) or completely flatten the input. We want the first for losses like Cross Entropy, and the second for pretty much anything else.
def CrossEntropyLossFlat(*args, axis:int=-1, # Class axis weight:NoneType=None, ignore_index:int=-100, reduction:str='mean', flatten:bool=True, # Flatten `inp` and `targ` before calculating loss floatify:bool=False, # Convert `targ` to `float` is_2d:bool=True, # Whether `flatten` keeps one or two channels when applied):
Same as nn.CrossEntropyLoss, but flattens input and target.
tst = CrossEntropyLossFlat(reduction='none')output = torch.randn(32, 5, 10)target = torch.randint(0, 10, (32,5))#nn.CrossEntropy would fail with those two tensors, but not our flattened version._ = tst(output, target)with expect_fail(): nn.CrossEntropyLoss()(output,target)#Associated activation is softmaxtest_eq(tst.activation(output), F.softmax(output, dim=-1))#This loss function has a decodes which is argmaxtest_eq(tst.decodes(output), output.argmax(dim=-1))
#In a segmentation task, we want to take the softmax over the channel dimensiontst = CrossEntropyLossFlat(axis=1)output = torch.randn(32, 5, 128, 128)target = torch.randint(0, 5, (32, 128, 128))_ = tst(output, target)test_eq(tst.activation(output), F.softmax(output, dim=1))test_eq(tst.decodes(output), output.argmax(dim=1))
Focal Loss is the same as cross entropy except easy-to-classify observations are down-weighted in the loss calculation. The strength of down-weighting is proportional to the size of the gamma parameter. Put another way, the larger gamma the less the easy-to-classify observations contribute to the loss.
def FocalLossFlat(*args, gamma:float=2.0, # Focusing parameter. Higher values down-weight easy examples' contribution to loss axis:int=-1, # Class axis weight:NoneType=None, reduction:str='mean', **kwargs):
Same as CrossEntropyLossFlat but with focal paramter, gamma. Focal loss is introduced by Lin et al. https://arxiv.org/pdf/1708.02002.pdf. Note the class weighting factor in the paper, alpha, can be implemented through pytorch weight argument passed through to F.cross_entropy.
def FocalLoss( gamma:float=2.0, # Focusing parameter. Higher values down-weight easy examples' contribution to loss weight:torch.Tensor=None, # Manual rescaling weight given to each class reduction:str='mean', # PyTorch reduction to apply to the output):
Same as nn.Module, but no need for subclasses to call super().__init__
#Compare focal loss with gamma = 0 to cross entropyfl = FocalLossFlat(gamma=0)ce = CrossEntropyLossFlat()output = torch.randn(32, 5, 10)target = torch.randint(0, 10, (32,5))test_close(fl(output, target), ce(output, target))#Test focal loss with gamma > 0 is different than cross entropyfl = FocalLossFlat(gamma=2)test_ne(fl(output, target), ce(output, target))
#In a segmentation task, we want to take the softmax over the channel dimensionfl = FocalLossFlat(gamma=0, axis=1)ce = CrossEntropyLossFlat(axis=1)output = torch.randn(32, 5, 128, 128)target = torch.randint(0, 5, (32, 128, 128))test_close(fl(output, target), ce(output, target), eps=1e-4)test_eq(fl.activation(output), F.softmax(output, dim=1))test_eq(fl.decodes(output), output.argmax(dim=1))
def BCEWithLogitsLossFlat(*args, axis:int=-1, # Class axis floatify:bool=True, # Convert `targ` to `float` thresh:float=0.5, # The threshold on which to predict weight:NoneType=None, reduction:str='mean', pos_weight:NoneType=None, flatten:bool=True, # Flatten `inp` and `targ` before calculating loss is_2d:bool=True, # Whether `flatten` keeps one or two channels when applied):
Same as nn.BCEWithLogitsLoss, but flattens input and target.
tst = BCEWithLogitsLossFlat()output = torch.randn(32, 5, 10)target = torch.randn(32, 5, 10)_ = tst(output, target)output = torch.randn(32, 5)target = torch.randint(0,2,(32, 5))#nn.BCEWithLogitsLoss would fail with int targets but not our flattened version._ = tst(output, target)with expect_fail(): nn.BCEWithLogitsLoss()(output,target)tst = BCEWithLogitsLossFlat(pos_weight=torch.ones(10))output = torch.randn(32, 5, 10)target = torch.randn(32, 5, 10)_ = tst(output, target)#Associated activation is sigmoidtest_eq(tst.activation(output), torch.sigmoid(output))
def LabelSmoothingCrossEntropy( eps:float=0.1, # The weight for the interpolation formula weight:torch.Tensor=None, # Manual rescaling weight given to each class passed to `F.nll_loss` reduction:str='mean', # PyTorch reduction to apply to the output):
Same as nn.Module, but no need for subclasses to call super().__init__
a reduction attribute, that will be used when we call Learner.get_preds
weight attribute to pass to BCE.
an activation function that represents the activation fused in the loss (since we use cross entropy behind the scenes). It will be applied to the output of the model when calling Learner.get_preds or Learner.predict
a decodes function that converts the output of the model to a format similar to the target (here indices). This is used in Learner.predict and Learner.show_results to decode the predictions
def LabelSmoothingCrossEntropyFlat(*args, axis:int=-1, # Class axis eps:float=0.1, reduction:str='mean', flatten:bool=True, # Flatten `inp` and `targ` before calculating loss floatify:bool=False, # Convert `targ` to `float` is_2d:bool=True, # Whether `flatten` keeps one or two channels when applied):
#These two should always equal each other since the Flat version is just passing data throughlmce = LabelSmoothingCrossEntropy()lmce_flat = LabelSmoothingCrossEntropyFlat()output = torch.randn(32, 5, 10)target = torch.randint(0, 10, (32,5))test_close(lmce(output.transpose(-1,-2), target), lmce_flat(output,target))
We present a general Dice loss for segmentation tasks. It is commonly used together with CrossEntropyLoss or FocalLoss in kaggle competitions. This is very similar to the DiceMulti metric, but to be able to derivate through, we replace the argmax activation by a softmax and compare this with a one-hot encoded target mask. This function also adds a smooth parameter to help numerical stabilities in the intersection over union division. If your network has problem learning with this DiceLoss, try to set the square_in_union parameter in the DiceLoss constructor to True.
def DiceLoss( axis:int=1, # Class axis smooth:float=1e-06, # Helps with numerical stabilities in the IoU division reduction:str='sum', # PyTorch reduction to apply to the output square_in_union:bool=False, # Squares predictions to increase slope of gradients):
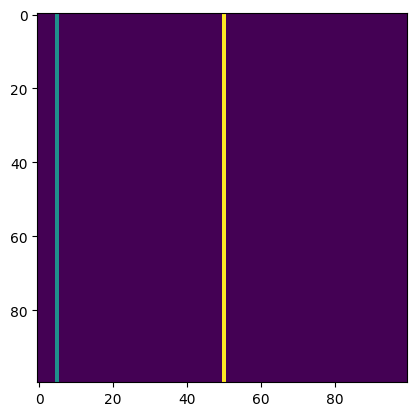
As a test case for the dice loss consider satellite image segmentation. Let us say we have three classes: Background (0), River (1) and Road (2). Let us look at a specific target
Nearly everything is background in this example, and we have a thin river at the left of the image as well as a thin road in the middle of the image. If all our data looks similar to this, we say that there is a class imbalance, meaning that some classes (like river and road) appear relatively infrequently. If our model just predicted “background” (i.e. the value 0) for all pixels, it would be correct for most pixels. But this would be a bad model and the diceloss should reflect that
model_output_all_background = torch.zeros(3, 100,100)# assign probability 1 to class 0 everywhere# to get probability 1, we just need a high model output before softmax gets appliedmodel_output_all_background[0,:,:] =100
# add a batch dimensionmodel_output_all_background = torch.unsqueeze(model_output_all_background,0)target = torch.unsqueeze(target,0)
Our dice score should be around 1/3 here, because the “background” class is predicted correctly (and that for nearly every pixel), but the other two clases are never predicted correctly. Dice score of 1/3 means dice loss of 1 - 1/3 = 2/3:
You could easily combine this loss with FocalLoss defining a CombinedLoss, to balance between global (Dice) and local (Focal) features on the target mask.
# Tests to catch future changes to pickle which cause some loss functions to be 'unpicklable'.# This causes problems with `Learner.export` as the model can't be pickled with these particular loss funcitons.losses_picklable = [ (BCELossFlat(), True), (BCEWithLogitsLossFlat(), True), (CombinedLoss(), True), (CrossEntropyLossFlat(), True), (DiceLoss(), True), (FocalLoss(), True), (FocalLossFlat(), True), (L1LossFlat(), True), (LabelSmoothingCrossEntropyFlat(), True), (LabelSmoothingCrossEntropy(), True), (MSELossFlat(), True),]for loss, picklable in losses_picklable:try: pickle.dumps(loss, protocol=2)except (pickle.PicklingError, TypeError) as e:if picklable:# Loss was previously picklable but isn't currentlyraise e